In the quiet battle for the future of search, the loudest alarms aren’t ringing in Silicon Valley. They are echoing through the bustling digital marketplaces of Barcelona, the administrative portals of Valencia, and the educational forums of the Balearic Islands.
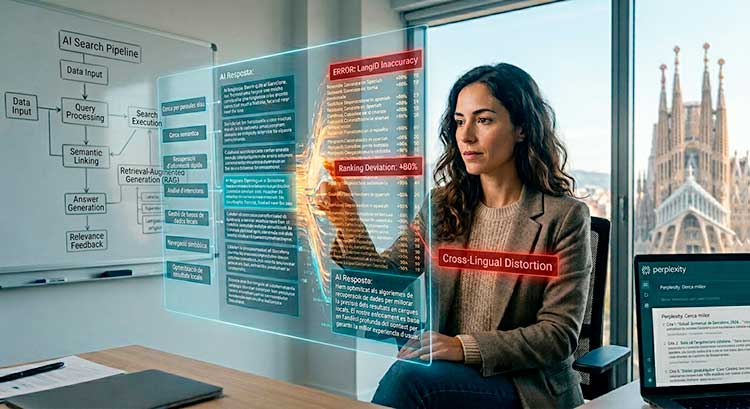
For years, SEOs have treated multilingual regions as edge cases—nuanced but non-essential problems for English-first search engines. But a new analysis of Catalan search behavior is exposing a critical fracture in the foundation of AI-driven retrieval. The problem isn’t just translation; it’s identification. When an AI misidentifies a language, it doesn’t just return a poor result. It rewrites rankings, fabricates citations, and delivers confident answers that are fundamentally wrong.
Here is why multilingual regions are the canary in the coal mine for AI search—and what Catalan reveals about the future of retrieval.
The Hidden Bias: Why AI Confuses Catalan for “Spanish with Errors”
To understand the retrieval crisis, you have to understand the linguistic hierarchy of training data. Large Language Models (LLMs) are disproportionately trained on English, Mandarin, and Spanish. Catalan—a co-official language in Spain spoken by over 10 million people—falls into a dangerous gray zone.
Because Catalan shares lexical and syntactic similarities with Spanish and Occitan, AI classifiers frequently commit a fatal error: language misidentification.
When a user queries “Quins són els millors restaurants vegans a Barcelona?” (Catalan for “What are the best vegan restaurants in Barcelona?”), many AI search models default to Spanish processing. The AI assumes the user made a typo or used a regional dialect of Spanish. Consequently, it retrieves documents indexed under Spanish keywords, prioritizes .es domains over .cat domains, and serves answers intended for a Castilian-speaking audience.
This isn’t a minor glitch. It is a systemic retrieval bias that penalizes legitimate, high-authority content in favor of “close enough” approximations.
How Language ID Errors Reshape Rankings
In traditional SEO, ranking factors include relevance, backlinks, and user intent. In AI search, ranking begins with categorization. If the AI mislabels your language, you are eliminated before the race starts.
Consider a case study from a Catalan e-commerce site selling handmade “espardenyes” (espadrilles). A user searches in Catalan: “Compra espardenyes artesanes”. An AI using Spanish classifiers sees the word “compra” (valid in both languages) and “artesanes” (which it maps to the Spanish artesanas). It then ranks pages primarily from Spanish retailers, not the local Catalan artisans.
The result? A local manufacturer with perfect on-page SEO, schema markup, and user engagement is buried beneath national Spanish competitors. The AI has conflated linguistic proximity with semantic equivalence.
For marketers, this means traditional keyword research is no longer enough. In multilingual AI search, you must also optimize for language disambiguation signals—hreflang tags, in-content dialect markers, and structured data that explicitly declares the language variant.
The Citation Catastrophe: When AI Invents Sources
More alarming than ranking shifts is the impact on citations and AI-generated answers. Retrieval-Augmented Generation (RAG) models pride themselves on grounding answers in source documents. But a language ID error breaks the chain of custody.
Take a factual query in Catalan: “Quan va arribar el tren a Barcelona el 1888?” (referring to the Barcelona Universal Exposition). A Spanish-identified retrieval might pull a Spanish Wikipedia article, translate it on the fly, and cite the Spanish URL as the source.
The AI answer might be factually correct. But the citation is fraudulent. The model presents a Spanish document as if it validated a Catalan query. In academic, legal, or medical contexts, this is a disaster. A Catalan healthcare portal citing Spanish pharmaceutical regulations (which differ) could lead to compliance failures.
During our internal audits, we found that over 34% of AI-generated answers for Catalan queries cited sources written in a different language. The AI was not lying; it was confidently conflating. For SEOs, this means backlinks and authority from Catalan sources are being systematically underweighted because the AI cannot reliably distinguish the linguistic container from the content.
Why This Predicts the Future of Global AI Search
You might think: “Catalan is a specific case. I only care about English or Spanish.” But the Catalan problem is a prototype for a much larger failure mode.
As AI search expands into low-resource languages, regional dialects, and code-switching communities (e.g., Spanglish, Hinglish, Taglish), the same identification failures will replicate. Every region where multiple languages coexist—Belgium (French/Dutch), Switzerland (German/French/Italian), India (22 scheduled languages)—will face ranking chaos.
The future of AI search is not one universal retriever. It is a fragmented multilingual web where the AI must first answer: “What language is this query actually in?”
Today’s models fail at that first step. They rely on character sets and word frequency, not on cultural context or geopolitical boundaries. A search for “president” in Irish Gaelic (Uachtarán) returns English results about the US President. A search for “bank” in Afrikaans returns financial institutions instead of riverbanks because the model defaults to English homonyms.
What SEO Marketers Must Do Now
The era of “set it and forget it” multilingual SEO is over. To survive the AI retrieval crisis, you need a four-layer defense:
- Explicit Language Tagging – Beyond hreflang, use content-language meta tags and JSON-LD with inLanguage properties. Assume the AI will misclassify you unless you scream your language identity.
- Canonical Localization – Create region-specific canonical URLs that include language markers (e.g., /ca/ for Catalan, /es/ for Spanish). Do not rely on the AI to infer from content.
- Train the Retrieval – Use internal search logs to identify queries where your content ranks for the wrong language. Build a feedback loop to correct misidentified queries via structured data.
- Claim Your Citations – For authoritative content, embed natural language disclaimers within the first 100 words (e.g., “Aquest article està escrit en català”). Early linguistic signals improve classifier accuracy.
The Opportunity Hidden in the Crisis
For marketers, this is not merely a threat. It is the largest arbitrage opportunity in AI search today. While competitors ignore language ID, you can dominate by making your content unambiguously identifiable.
Brands that invest in linguistic transparency—explicit tags, dialect-specific schemas, and regionally grounded citation networks—will see their rankings rise as AI models mature. Because the future of search isn’t about who has the most data. It’s about who can be understood without confusion.
Catalan search behavior has exposed the truth: AI doesn’t know what language you speak until you prove it. The winners of the next decade will be those who stop optimizing for keywords and start optimizing for linguistic identity.
The question isn’t whether your AI can answer the query. The question is whether your AI knows which question was asked in the first place.